Astra vs Fable: GPT 6.2 Astra and Claude Fable 5.2 on the same tasks
Astra vs Fable: GPT 6.2 Astra and Claude Fable 5.2 tied on 5 graded API tasks. Fable wrote 3.5x the tokens, finished sooner and billed 6.5x per call.
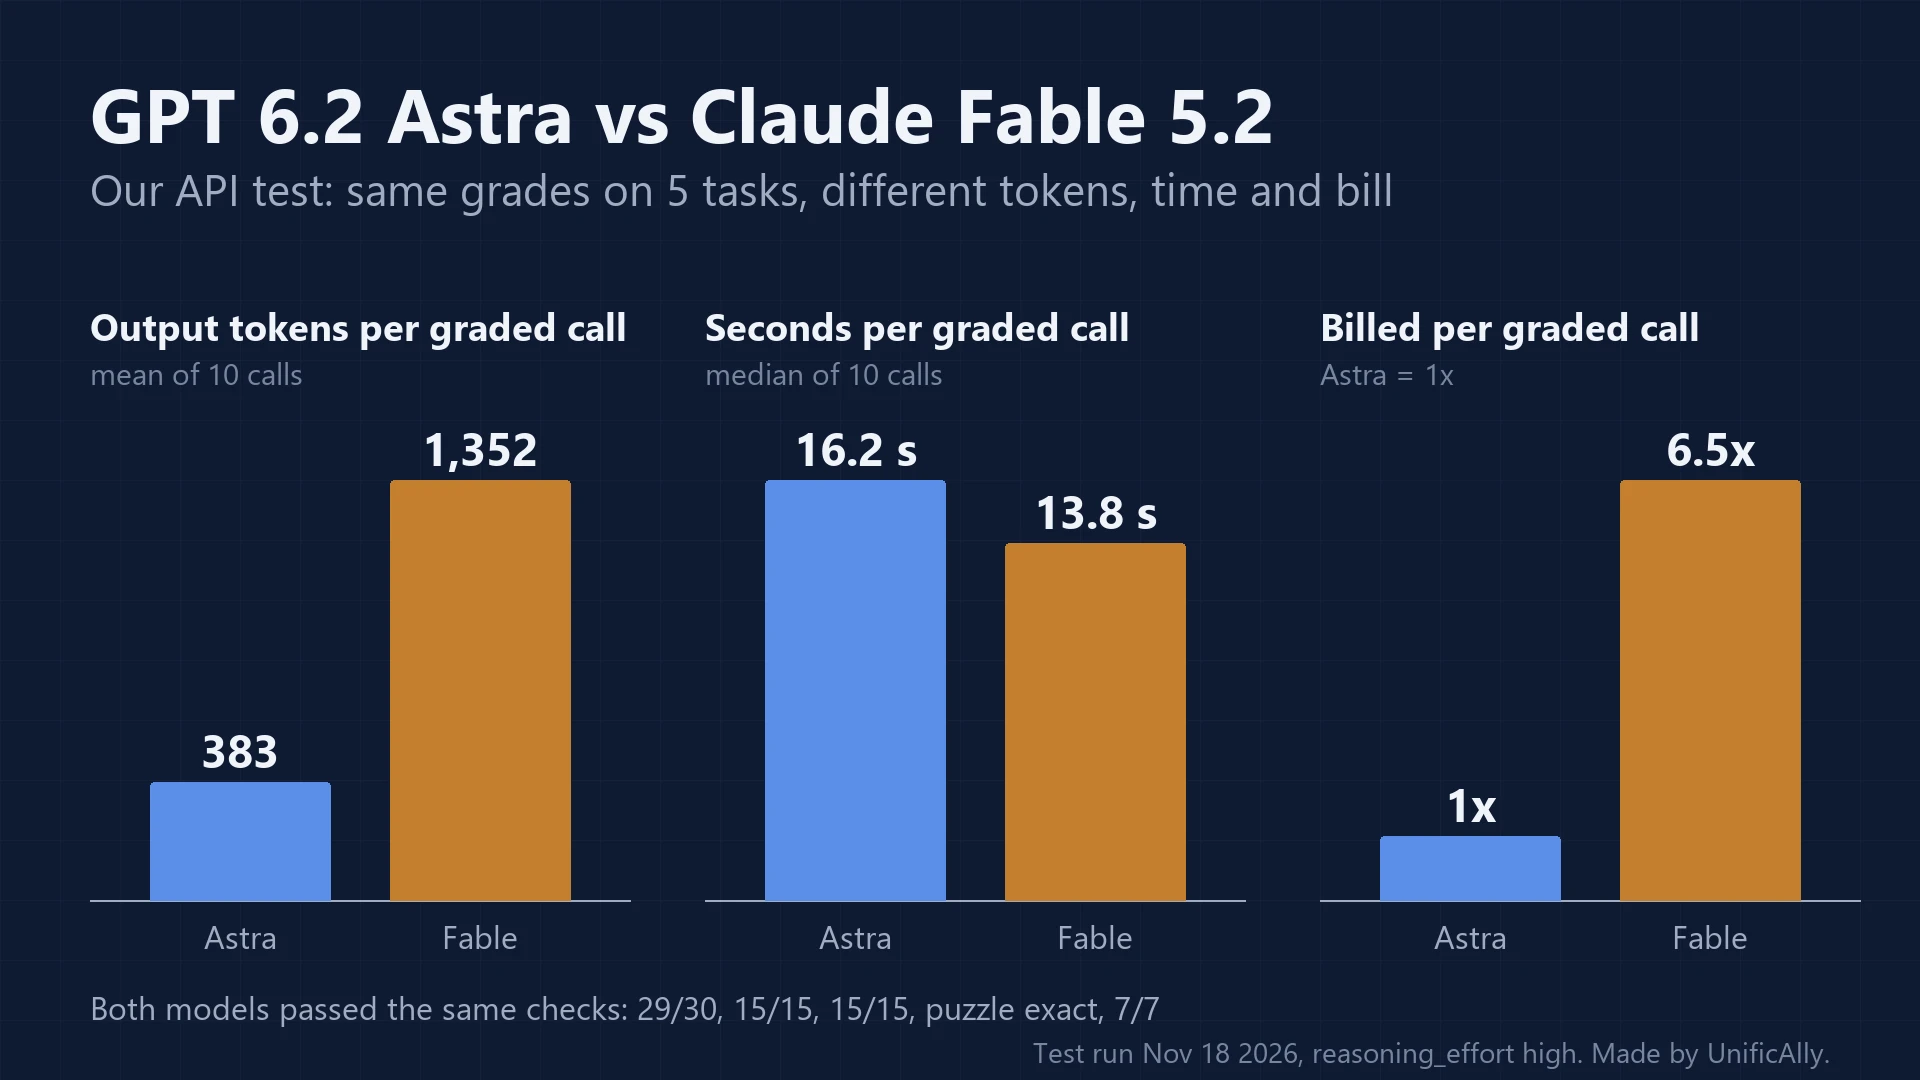
In Astra vs Fable, November 2026 edition, the answers tied; the invoice and the clock decided it. We sent the GPT 6.2 Astra API and the Claude Fable 5.2 API five graded tasks, twice each, on November 18, 2026. Both earned identical grades. Fable wrote 3.5 times as many output tokens, still finished first on four of the five tasks, and billed 6.5 times as much per graded call.
TL;DR: Route everyday API work to GPT 6.2 Astra, released by OpenAI on November 17, and keep Claude Fable 5.2, released by Anthropic on November 9, for jobs where its benchmark lead is real: it tops the Artificial Analysis Intelligence Index at high, xhigh and max effort (64.6 against 62.1 at max). Astra bills $6/1M tokens for output on prompts up to 272K tokens; Fable bills $12/1M tokens. Both are callable on UnificAlly today.
Six numbers that separate GPT 6.2 Astra from Claude Fable 5.2
- Our grades were a dead heat. Each model passed 29 of 30 parser cases in both runs, 15 of 15 bug-fix tests, all 15 extraction fields, the logic puzzle and all 7 format checks.
- Fable spends far more tokens. Mean output per graded call was 383 tokens on Astra and 1,352 on Fable.
- Fable is still quicker per call. Median time per graded call was 13.8 seconds on Fable and 16.2 on Astra, because Fable generates about twice as many tokens per second.
- Fable leads the independent index at matched effort. Artificial Analysis scores Fable 64.6, 62.2 and 61.8 at max, xhigh and high, against 62.1, 61.6 and 60.1 for Astra.
- Astra leads the agent and legal rows in OpenAI's own chart. Agents' Last Exam: 78.3% (Astra, xhigh) against 72.8% (Fable, max); Harvey LAB-AA: 15.0% against 7.2%.
- Human-vote data is thin. Astra is on no Arena board yet (the newest board update predates its release), and Fable appears only on WebDev, where it ranks first.
GPT 6.2 Astra vs Claude Fable 5.2: specs and API rules side by side
The two flagships list at the same official price and nearly the same window, so the differences that bite sit in the request rules.
| GPT 6.2 Astra | Claude Fable 5.2 | |
|---|---|---|
| Maker, release date | OpenAI, November 17, 2026 | Anthropic, November 9, 2026 |
| Model ID on UnificAlly | openai/gpt-6.2-astra | anthropic/claude-fable-5-2 |
| Context window | 1,050,000 tokens (922,000 max input) | 1M tokens |
| Max output | 128,000 tokens | 128K tokens |
| Input and output | text and images in, text out | text and images in, text out |
| Knowledge cutoff | May 18, 2026 | June 2026 |
| Reasoning effort values | low, medium, high, xhigh, max; none is rejected | low, medium, high, xhigh, max; thinking cannot be switched off |
| Default effort | not listed in OpenAI's model docs (checked November 18, 2026) | high in the API, Medium in Claude's own apps |
| Sampling fields | no rule listed in OpenAI's model docs | leave out temperature, top_p, top_k |
| Long prompts | above 272K input tokens the whole request bills at a higher tier | one rate across the full 1M window |
| Output rate on UnificAlly | $6/1M tokens (prompt up to 272K) | $12/1M tokens |
| Official list price (reference) | $8 input, $40 output, $0.40 cache read per 1M | $8 input, $40 output, $0.20 cache read per 1M |
| Artificial Analysis index, max effort | 62.1 (rank 3 of 120) | 64.6 (rank 1 of 120) |
GPT 6.2 Astra and Claude Fable 5.2 carry the same $8 and $40 official list price per million tokens, so any difference in what a job costs at list price comes from how many tokens each model writes.
A note on names: OpenAI writes GPT-6.2 Astra and the API ID is gpt-6.2-astra; Anthropic's ID is claude-fable-5-2. Searches shorten the pair to "Astra vs Fable", "GPT 6.2 vs Claude Fable 5.2" or "GPT 6.2 Astra vs Fable 5.2", and all of them mean the two models in this table. Mythos 5.2, per Anthropic, is Fable 5.2 itself with the cyber and biology safeguards lifted, and only organizations Anthropic has verified can call it.
Three rules outside the table decide most migrations. Fable rejects requests that force a tool through tool_choice set to any or a named tool, so leave it at auto. Fable keeps prompts for 30 days for safety monitoring unless Anthropic has approved zero data retention for the account. Astra's cyber safeguards were tightened at launch and, by OpenAI's own account in the GPT 6.2 announcement, also block some legitimate security testing; Fable's classifiers block most penetration testing and exploit work outright, per Anthropic's Fable 5.2 launch post.
GPT 6.2 Astra vs Claude Fable 5.2: our test results on five graded tasks
On November 18, 2026 we ran both models through the UnificAlly API with reasoning_effort set to high, no temperature and no max_tokens, and the same system line: "You are a careful senior engineer. Follow the output format exactly." Five tasks were graded by code we wrote before seeing any reply, two runs each, so 10 graded calls per model. A sixth prompt asked for an SVG drawing that we show but do not score. Times are wall-clock seconds measured by our client; tokens and costs come from our task log.
| Test (2 runs each) | GPT 6.2 Astra | Claude Fable 5.2 | Winner |
|---|---|---|---|
T1: Python parse_duration from a written spec, 30 hidden tests | 29 of 30, both runs | 29 of 30, both runs | Tie |
| T2: fix four planted bugs in a TTL cache, 15 hidden tests | 15 of 15, both runs | 15 of 15, both runs | Tie |
| T3: messy order email to JSON, 15 fields | 15 of 15, both runs | 15 of 15, both runs | Tie |
| T4: five-person seating puzzle with one solution | exact, both runs | exact, both runs | Tie |
| T5: launch note with 7 checked constraints | 7 of 7, both runs | 7 of 7, both runs | Tie |
| Mean output tokens per graded call | 383 | 1,352 | Astra |
| Median seconds per graded call | 16.2 | 13.8 | Fable |
| Billed, all 10 graded calls | $0.0265 | $0.1735 | Astra |
Across ten graded calls each, GPT 6.2 Astra and Claude Fable 5.2 scored the same on every check, and Fable cost 6.5 times as much per graded call on UnificAlly.
T1, the parser. Both models missed the same single case: ' 45s ' with spaces around it. Our spec allowed whitespace only between components, so the string should raise an error; both parsers strip the outer spaces first and return 45. Fable's docstring even states that rule as a feature. Both used Fraction for exact decimal math, so '1.25m' (75 seconds) passes and '0.3s' raises. Fable's answer ran 51 to 64 lines with a docstring and a type check; Astra's ran 35 lines.
T2, the cache. The class had four planted bugs: get() did not refresh recency, expired keys stayed in len(), set() evicted the newest entry and also evicted on overwrite, and expiry used > where >= was right. Both returned classes that passed all 15 tests with a fake clock.
T3, the email. The traps were a quantity raised from 2 to 3 in a later reply, a cancelled salad bowl, prices written as €12,50, a date written "the 3rd of December", an expired discount code and a forwarded signature with a different address and city. Both got every field, including "requested_delivery_date": "2026-12-03" and Graz rather than the Vienna head office. Fable answered in 5.4 seconds, Astra in 9.3.
T4, the puzzle. Seventeen clues, one valid seating (we proved uniqueness by brute force before the run). Both returned Chloe, Elena, Dmitri, Ben, Ava. Astra needed about 600 tokens and 32 seconds; Fable used about 1,550 tokens and took 16.
T5, the launch note. Exactly four sentences, a question in sentence two, 60 to 80 words, no banned marketing words, and the number 42 exactly once. Both passed all seven checks, with word counts from 68 to 77. Fable used the 42 to invent a beta result ("cut that reconciliation work by 42 percent"); Astra made it the number of sample orders in a sandbox. Neither broke a rule, but only one made up a performance claim for a product that does not exist.
T6, the SVG drawing (shown, not scored). The prompt asked for a lighthouse on a cliff at night with a sailboat lit inside the beam, 800 by 600, no scripts. All four drawings were valid SVG with no external references, and each put the boat in or at the edge of the beam. Astra drew a wide beam with the boat near its lower edge both times; Fable's high-effort run added a second beam and a glow pool around the hull.
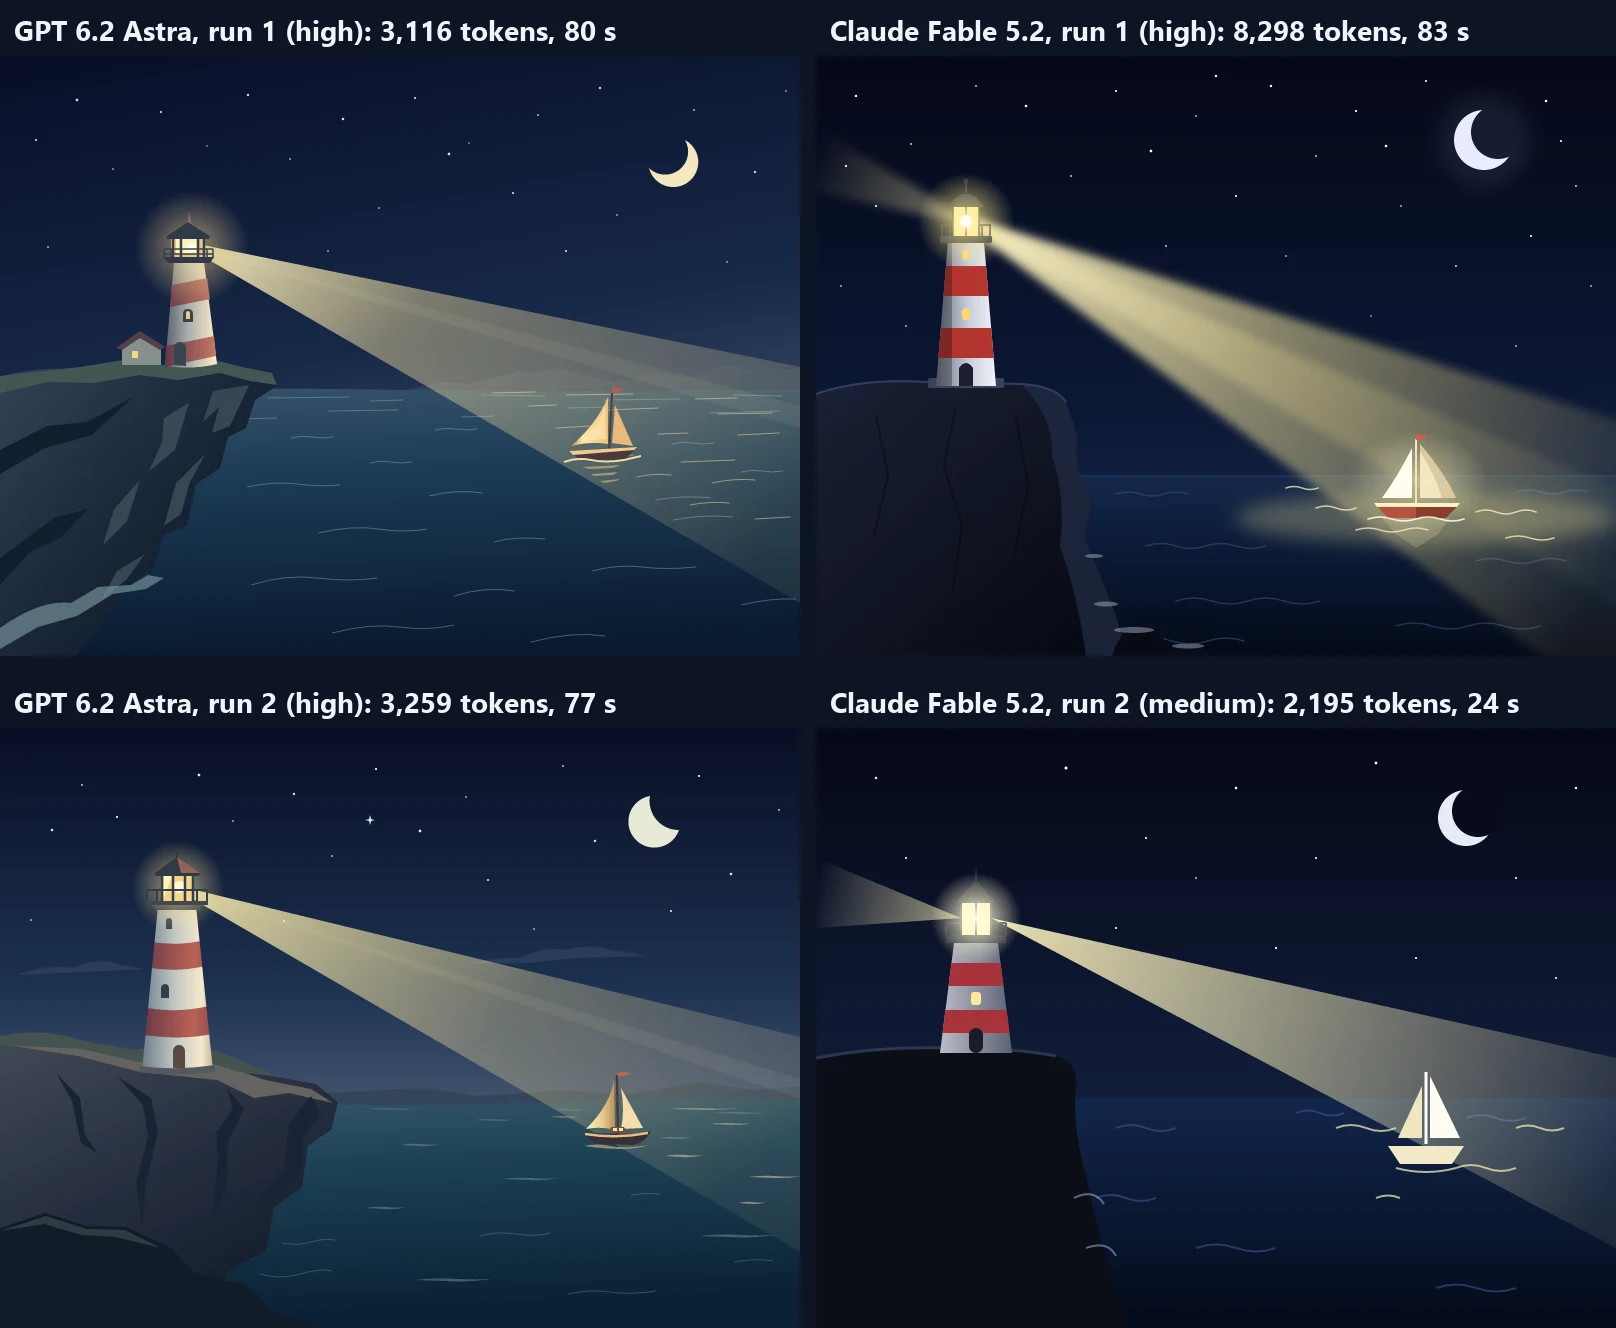
That prompt also showed how much Fable's output length swings at high effort. Our test client gave up after 85 seconds, and three Fable replies at high effort ran past it; each was billed, with 9,490 to 16,153 output tokens, but never reached us. The successful high-effort reply took 8,298 tokens in 82.6 seconds, so for run 2 we dropped Fable to medium, which answered in 2,195 tokens and 23.8 seconds. One Astra reply was lost the same way. The four lost replies cost $0.4332 on Fable and $0.0207 on Astra, kept out of the graded totals above.
What the tests settle. Five ties on correctness, so on short, checkable work neither model is smarter in a way we could measure. The measurable differences were tokens, time and money: Astra was cheaper on all five tasks, Fable faster on four.
What they do not settle. Ten graded calls per model, one effort setting, one day. These tasks take seconds; the benchmark gaps below come from agent runs that take minutes or hours, which this test never touched.
Why Claude Fable 5.2 finished sooner while writing 3.5x more than GPT 6.2 Astra
Wall-clock time per call goes to Claude Fable 5.2 because it writes faster, not because it writes less. Artificial Analysis measures Fable at about 110 output tokens per second on every effort tier, against 53 to 56 for GPT 6.2 Astra (pulled November 18, 2026).
Our per-task medians show both sides of that:
| Task | GPT 6.2 Astra | Claude Fable 5.2 | Faster |
|---|---|---|---|
| T1 parser | 19.9 s, 491 tokens | 27.8 s, 2,714 tokens | Astra |
| T2 cache fix | 14.9 s, 421 tokens | 13.8 s, 1,252 tokens | Fable |
| T3 extraction | 9.3 s, 166 tokens | 5.4 s, 352 tokens | Fable |
| T4 puzzle | 32.3 s, 600 tokens | 16.2 s, 1,557 tokens | Fable |
| T5 launch note | 15.1 s, 236 tokens | 10.9 s, 886 tokens | Fable |
GPT 6.2 Astra took 32.3 seconds to write about 600 tokens on the puzzle, while Claude Fable 5.2 wrote 1,557 tokens in 16.2. Astra's usage block reports its reasoning tokens separately (566 to 570 of those 600 on T4), so most of that wait was thinking before the first visible character. Fable folds its adaptive thinking into the output count without a split.
Astra still won T1, the one task where Fable wrote more than 2,500 tokens. The crossover is length: once a reply runs to a few thousand tokens, Fable's speed advantage stops covering its extra text. At the Artificial Analysis high setting the same pattern holds over a full benchmark run, with Fable at 14.9 minutes per index task and Astra at 5.3, because Fable wrote 85.3M output tokens to Astra's 20.0M.
Verdict on speed: for short, interactive calls Claude Fable 5.2 usually answers first; for long jobs GPT 6.2 Astra gets done sooner because it says less.
Claude Fable 5.2 vs GPT 6.2 Astra on benchmarks, with the effort setting on every number
The broad independent boards favour Claude Fable 5.2, and GPT 6.2 Astra wins a set of narrower rows. The numbers below were pulled on November 18, 2026 from each board's own page; where the two models ran at different settings, both are named.
| Board (setting) | GPT 6.2 Astra | Claude Fable 5.2 | Leader |
|---|---|---|---|
| Artificial Analysis Intelligence Index v5.0.1, max | 62.1 | 64.6 | Claude Fable 5.2 |
| Same index, xhigh | 61.6 | 62.2 | Claude Fable 5.2 |
| Same index, high | 60.1 | 61.8 | Claude Fable 5.2 |
| Same index, medium | 57.0 | 56.4 | GPT 6.2 Astra |
| Same index, low | 45.7 | 53.9 | Claude Fable 5.2 |
| Vals Index v2.2 (Astra max, Fable high) | 67.66% | 71.31% | Claude Fable 5.2 |
| Terminal-Bench 4.1, max (Codex vs Claude Code harness) | 62.1% ±2.3 | 65.8% ±2.8 | Claude Fable 5.2 |
| HLE-Diamond, max (Artificial Analysis) | 72.2% | 80.2% | Claude Fable 5.2 |
| Terminal-Bench-Science 0.1, max (Artificial Analysis) | 78.1% | 73.3% | GPT 6.2 Astra |
| Terminal-Bench 4.0, max (Artificial Analysis) | 64.1% | 59.6% | GPT 6.2 Astra |
| ARC-AGI-2 semi-private, max | 95.8% | 92.5% | GPT 6.2 Astra |
| ARC-AGI-3 standard harness, high | 58.0% | 79.3% | Claude Fable 5.2 |
| LiveBench 2.0 overall (Astra max, Fable xhigh) | 84.9 | 84.9 | Tie |
| LiveBench 2.0 coding / agentic | 91.9 / 70.8 | 79.2 / 82.9 | Split |
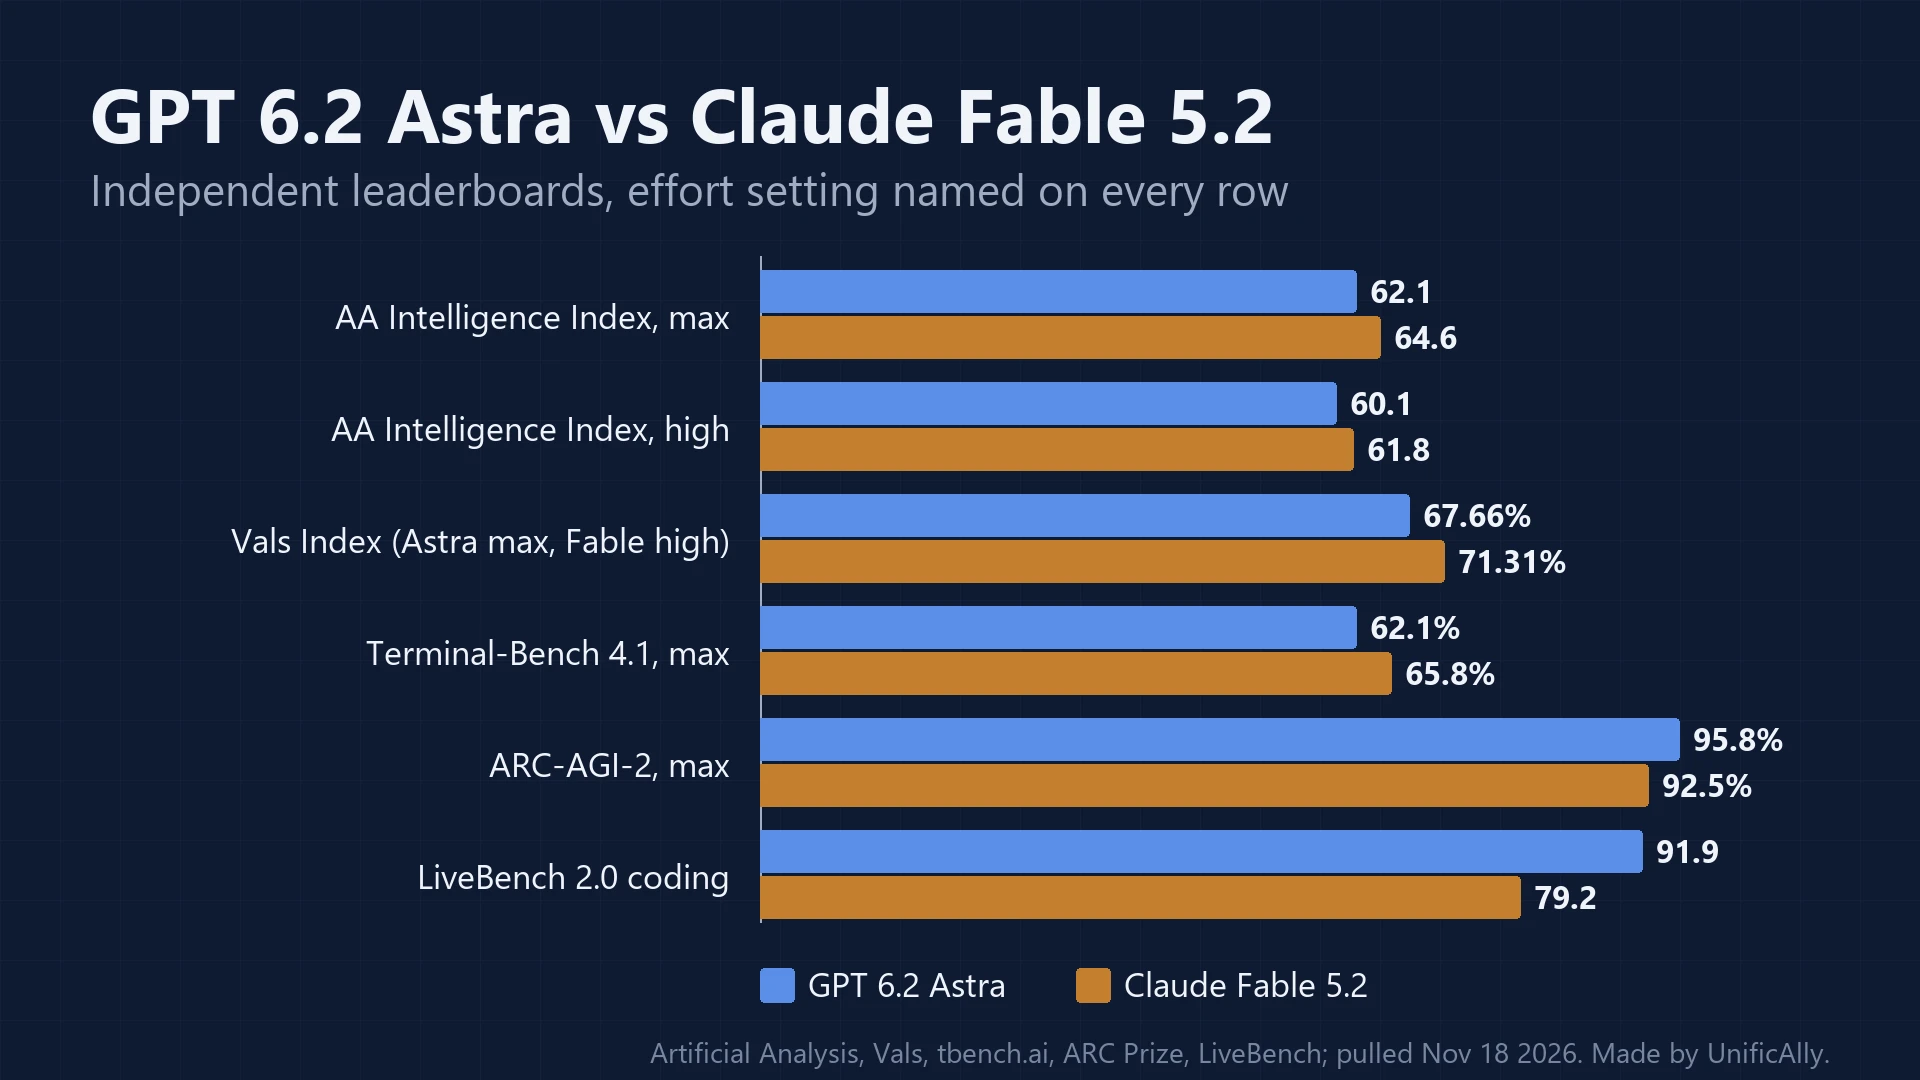
Claude Fable 5.2 scores higher than GPT 6.2 Astra on the Artificial Analysis Intelligence Index at max, xhigh, high and low effort, with Astra ahead only at medium (57.0 against 56.4), and on the Vals Index Fable at high effort beats Astra at max. Where Fable pulls furthest ahead is knowledge-heavy reasoning: 8 points on HLE-Diamond and 21 points on ARC-AGI-3 at high effort. Astra keeps the science-in-a-terminal row, the Terminal-Bench 4.0 component and ARC-AGI-2, and on LiveBench it beats Fable on coding by 12.7 points while losing agentic by 12.1. On Arena's WebDev board Fable 5.2 at xhigh is first at 1826 from 1,445 votes; that board was last updated November 13, before Astra existed.
OpenAI's launch chart adds rows only OpenAI has run, and they favour Astra: Agents' Last Exam v1.1 at 78.3% (xhigh) against 72.8% (Fable, max), AutomationBench 52.4% against 51.4%, Harvey LAB-AA legal work 15.0% against 7.2%, and GDPval v2 at 50.4% against 44.8%, where Fable spent 222,344 output tokens to Astra's 35,812. Read them as vendor numbers. OpenAI's own footnote says the Fable score on Agents' Last Exam leaves out nine tasks that used a fallback model, and in the same chart Fable still wins FrontierCode 2.0 (49.1% at xhigh against 44.2% at max) and BenchCAD 2.1 (83.5 against 82.5).
From GPT 6 Astra vs Claude Fable 5.1 to GPT 6.2 Astra vs Claude Fable 5.2: the lead switched
The September matchup went to OpenAI, and the November one does not. In Anthropic's own table, which lists GPT 6 Astra beside both Fable versions, GPT 6 Astra beat Claude Fable 5.1 on 7 of 10 shared rows, including FrontierCode 2.0 (42.8% against 32.4%) and Terminal-Bench-Science (68.1% against 52.6%). Fable 5.1 kept OSWorld 2.1, Humanity's Last Exam and AA-Briefcase. Fable 5.2 now beats GPT 6 Astra on all ten of those rows, so Fable 5.1 vs GPT 6 Astra reviews from September describe a race that has since turned around.
OpenAI answered with a bigger step than the version number suggests. In its launch chart GPT 6.2 Astra gains 5.2 points over GPT 6 Astra on Agents' Last Exam, 11 points on AutomationBench and 9 points on Terminal-Bench-Science, and reaches 50.4% on GDPval v2 with 22% fewer output tokens than its predecessor. So the gap that searchers of "gpt 6 astra vs fable 5.1" saw has flipped, then narrowed: Fable leads the matched-effort index at max by 2.5 points (64.6 against 62.1).
Prices moved in the same direction on both sides. OpenAI cut GPT 6.2 Astra's input and output list prices 20% below GPT 6 Astra and cached input 60%. Anthropic cut Fable from $10 and $50 per million tokens on 5.1 to $8 and $40 on 5.2, and says Fable 5.2 writes output up to 30% faster than 5.1. Any GPT 6 Astra vs Fable comparison written before November should be read with both cuts in mind.
GPT 6.2 Astra vs Claude Fable 5.2: tokens and cost per task
On UnificAlly the cost gap between GPT 6.2 Astra and Claude Fable 5.2 has two parts: Fable writes more tokens, and each output token costs more.
| Rate on UnificAlly, per 1M tokens | GPT 6.2 Astra (prompt up to 272K) | Claude Fable 5.2 |
|---|---|---|
| Input | $1.20/1M tokens | $2.40/1M tokens |
| Output | $6/1M tokens | $12/1M tokens |
| Cache read | $0.06/1M tokens | $0.06/1M tokens |
| Cache creation | $1.50/1M tokens | $3/1M tokens |
Astra's rates above apply while the prompt stays at or under 272K tokens. Past that line the entire request moves to Astra's long-prompt tier, listed in the full rate card below; Fable has no such tier.
| Model | Option | Our rate |
|---|---|---|
| GPT 6.2 Astra | input (prompt up to 272k) | $1.20/1M tokens |
| output (prompt up to 272k) | $6/1M tokens | |
| cache read (prompt up to 272k) | $0.06/1M tokens | |
| cache creation (prompt up to 272k) | $1.50/1M tokens | |
| input (prompt over 272k) | $2.40/1M tokens | |
| output (prompt over 272k) | $9/1M tokens | |
| cache read (prompt over 272k) | $0.12/1M tokens | |
| cache creation (prompt over 272k) | $3/1M tokens | |
| Claude Fable 5.2 | input | $2.40/1M tokens |
| output | $12/1M tokens | |
| cache read | $0.06/1M tokens | |
| cache creation | $3/1M tokens |
A worked example from our own traffic: 1,000 calls shaped like our graded set average 383 output tokens each on Astra and 1,352 on Fable. Output alone for those 1,000 calls comes to about $2.298 on Astra and $16.224 on Fable, and input adds little at a few hundred tokens per prompt. Thinking tokens bill as output on both models, which is why reasoning_effort is the main cost dial: Fable at medium wrote a quarter of the tokens of its successful high run on our SVG prompt.
Every OpenAI and Claude rate we sell is in our OpenAI API pricing guide and our Claude Fable 5.2 pricing guide.
Calling GPT 6.2 Astra and Claude Fable 5.2 with the same request
Both models answer on one OpenAI-compatible endpoint. This is the request shape behind every call in our test, here with the cache-fix prompt shortened:
curl -X POST https://direct-api.unifically.com/v1/chat/completions \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer YOUR_API_KEY" \
  -d '{
    "model": "openai/gpt-6.2-astra",
    "reasoning_effort": "high",
    "messages": [
      {"role": "system", "content": "You are a careful senior engineer. Follow the output format exactly."},
      {"role": "user", "content": "This TTL LRU cache has bugs. Return the corrected full class in one python block, no prose. Keep the public API."}
    ]
  }'
To send the same call to Fable, change model to anthropic/claude-fable-5-2 and keep temperature, top_p and top_k out of the body. Read the token counts from usage in the reply; on Astra the reasoning share is reported on its own line, which makes it easy to see when a high setting is buying thinking you do not need. Set your HTTP client timeout well above our 85 seconds, or set "stream": true, before sending Fable long-output work at high. Every parameter for each model is on the GPT 6.2 Astra model page and the Claude Fable 5.2 model page.
Which to route where: GPT 6.2 Astra or Claude Fable 5.2
| Dimension | Leader | Evidence |
|---|---|---|
| Correctness on short graded tasks | Tie | identical grades on 10 calls each |
| Cost per call on UnificAlly | GPT 6.2 Astra | 6.5x lower per graded call |
| Time per short call | Claude Fable 5.2 | 13.8 s against 16.2 s median |
| Broad independent index | Claude Fable 5.2 | 64.6 against 62.1 at max |
| Knowledge-heavy reasoning | Claude Fable 5.2 | HLE-Diamond 80.2% against 72.2% |
| Long agent tasks and legal work (vendor rows) | GPT 6.2 Astra | Agents' Last Exam 78.3% against 72.8%; Harvey LAB-AA 15.0% against 7.2% |
| Overall pick for production API traffic | GPT 6.2 Astra | same answers on our tasks at a fraction of the bill |
Send it to GPT 6.2 Astra when:
- the work is extraction, short code fixes, classification or formatted writing, where both models matched on every check and Astra cost about one sixth as much;
- prompts stay under 272K tokens, so Astra's lower tier applies;
- the job is long and output-heavy, since Astra wrote 22% fewer tokens than its predecessor on GDPval and 3.5x fewer than Fable in our run.
Send it to Claude Fable 5.2 when:
- a user is waiting on a short answer, because Fable answered first on four of our five tasks;
- the task leans on recall and hard reasoning, where Fable's 8-point HLE-Diamond lead and its ARC-AGI-3 margin are the largest gaps on the board;
- you build web front ends, where Fable is first on Arena's WebDev board and Astra has no rating yet;
- your prompts run past 272K tokens, because Fable keeps one rate across its 1M window.
Our recommendation: in Fable 5.2 vs Astra, GPT 6.2 Astra is the default and Claude Fable 5.2 is the escalation. Point production traffic at Astra, log the calls it gets wrong, and replay those on Fable at high. Paying 6.5 times as much for answers that came back identical in every one of our graded checks is hard to defend; paying it for the cases Astra fails is not. When even Astra is more model than the job needs, the Claude Fable 5.2 vs Opus 5.5 test shows how far down the Claude line routine work can go, and GPT 6.2 Sol is OpenAI's smaller option.
GPT 6.2 Astra vs Fable 5.2 FAQ
Is GPT 6.2 Astra better than Claude Fable 5.2?
Not on the broad boards: Claude Fable 5.2 scores 64.6 against 62.1 for GPT 6.2 Astra on the Artificial Analysis Intelligence Index at max effort, and leads at xhigh and high too. In our five graded API tasks the two tied on every check, and Astra cost 6.5 times less per call.
Which is better for coding, GPT 6.2 Astra or Claude Fable 5.2?
For agentic and web coding, Claude Fable 5.2: it leads FrontierCode 2.0 (49.1% at xhigh against 44.2% at max), Terminal-Bench 4.1 (65.8% against 62.1%, both max) and Arena WebDev, while GPT 6.2 Astra leads LiveBench coding (91.9 at max against 79.2 at xhigh). Both passed the same tests on our parser and bug-fix tasks.
Is GPT 6.2 Astra faster than Claude Fable 5.2?
Per short call, no: Claude Fable 5.2 had a median of 13.8 seconds per graded call in our test against 16.2 for GPT 6.2 Astra, since Fable writes about 110 tokens per second against Astra's 53 to 56. On long jobs Astra finishes sooner because it writes far fewer tokens.
How much does one task cost on GPT 6.2 Astra vs Claude Fable 5.2?
In our test, ten graded calls cost $0.0265 on GPT 6.2 Astra and $0.1735 on Claude Fable 5.2, a 6.5x gap. Fable wrote 3.5 times as many output tokens and pays $12/1M tokens for output against $6/1M tokens for Astra on UnificAlly.
What changed since GPT 6 Astra vs Claude Fable 5.1?
The lead switched sides. In Anthropic's table GPT 6 Astra beat Claude Fable 5.1 on 7 of 10 shared rows, while Fable 5.2 beats GPT 6 Astra on all 10. GPT 6.2 Astra then narrowed the gap, and both makers cut list prices to $8 input and $40 output per million tokens.
Is Claude Fable the same as ChatGPT?
No. Claude Fable 5.2 is Anthropic's model, used in the Claude apps and the Claude API, while ChatGPT is OpenAI's app, where GPT 6.2 Astra runs for Plus, Pro, Enterprise and Edu users. Asked through an API, a Claude Fable vs ChatGPT question becomes the GPT 6.2 Astra vs Claude Fable 5.2 choice this test measured.
Which model is as good as Claude Fable 5.2?
GPT 6.2 Astra comes closest: it trails Claude Fable 5.2 by 2.5 points on the Artificial Analysis index at max effort and matched it on all five of our graded tasks. Within Anthropic's line, Claude Opus 5.5 handled our earlier routine tasks just as well.
Both models are live now as the GPT 6.2 Astra API and the Claude Fable 5.2 API, with Claude Opus 5.5 for Claude traffic that does not need Fable.