Gemini 3.7 Flash API pricing: what Google's fast model costs, and how it benchmarks
Gemini 3.7 Flash API pricing per 1M tokens: Google deprecated it on October 8, 2026 and routes calls to 3.8 Flash. Our rate, benchmarks, and how to switch.
Gemini 3.7 Flash is the Flash model Google released on August 13, 2026 and deprecated on October 8, eight weeks later. Since that date Google routes every API call to gemini-3.7-flash on to Gemini 3.8 Flash. On UnificAlly the Gemini 3.7 Flash API still answers as google/gemini-3.7-flash at $0.225 / $1.125 per million input / output tokens, the same rate as 3.8 Flash.
TL;DR: Gemini 3.7 Flash pricing on our card equals Gemini 3.8 Flash pricing, and 3.8 Flash is the better model at that rate: 73.7% against 65.3% on DeepSWE v1.1, and #9 against #17 on Arena's text board (pulled November 16, 2026). Google no longer lists a separate 3.7 Flash price; its launch pricing story now belongs to 3.8 Flash, whose introductory rate runs through December 31, 2026. Change the model string to
google/gemini-3.8-flashfor new work. Existing 3.7 calls keep working on the same three endpoints.
Gemini 3.7 Flash in November 2026: retired by Google, still callable here
- Google retired it fast. Released August 13, deprecated October 8, with AI Studio no longer offering it and the API routing
gemini-3.7-flashrequests togemini-3.8-flash. Google says the endpoint itself is not shutting down. - Its price row is gone from Google's page. Gemini 3.8 Flash and 3.6 Flash both show an introductory rate through December 31, 2026 and a standard rate from January 1, 2027. 3.7 Flash shows nothing.
- The launch benchmarks still hold. Against 3.6 Flash it rose from 48.6% to 65.3% on DeepSWE v1.1 and from 34.4% to 43.6% on FrontierCode 1.1, per Google's model card.
- Its Arena standing slipped. It now sits at #17 on the text board with 1489 points, down from the #9 we recorded at launch, while 3.8 Flash holds #9.
- Speed can no longer be re-checked. Artificial Analysis marks 3.7 Flash deprecated and shows no live measurement, so the launch-week throughput figure below is history, not a current number.
What is Gemini 3.7 Flash?
Gemini 3.7 Flash is a Google DeepMind language model built on Gemini 3.6 Flash, aimed at coding, agent workflows and multi-step tasks, with support for agentic video understanding. It reads text, images, audio, video and PDFs and writes text. People type its name as "Gemini 3.7 Flash", "gemini-3.7-flash" and "3.7 Flash"; on UnificAlly the API model ID is google/gemini-3.7-flash.
| Attribute | Gemini 3.7 Flash |
|---|---|
| Developer | Google DeepMind |
| Type | Multimodal reasoning language model, Flash tier |
| Status | Deprecated by Google on October 8, 2026; API calls routed to Gemini 3.8 Flash |
| Release date | August 13, 2026 |
| Modality | Text, image, audio, video and PDF in; text out |
| Context window | 1,048,576 input tokens, 65,536 output tokens |
| Pricing | $0.225 input / $1.125 output per 1M tokens on UnificAlly |
| Availability | google/gemini-3.7-flash on UnificAlly; no longer selectable in Google AI Studio |
| API model ID | google/gemini-3.7-flash (UnificAlly), gemini-3.7-flash (Google) |
| License | Proprietary, API only |
Google's thinking levels for 3.7 Flash were low, medium (the default) and high. The minimal level from earlier Flash models returns an error, so even a one-word classification carries some thinking cost. The model card gives a knowledge cutoff of March 2026, with some domains only as current as January 2025.
Gemini 3.7 Flash benchmarks from Google's launch card
Google's August 2026 model card compared 3.7 Flash with its predecessor and two mid-tier rivals:
| Benchmark | Gemini 3.7 Flash | Gemini 3.6 Flash | Claude Sonnet 5 | GPT-5.6 Terra | Leader |
|---|---|---|---|---|---|
| FrontierCode 1.1 Main | 43.6% | 34.4% | 42.7% | 41.3% | 3.7 Flash |
| DeepSWE v1.1 | 65.3% | 48.6% | 53.8% | 69.6% | GPT-5.6 Terra |
| Terminal-bench 2.1 | 85.8% | 78.0% | 80.4% | 87.4% | GPT-5.6 Terra |
| Code Arena (web development, Elo) | 1588 | 1538 | 1541 | 1523 | 3.7 Flash |
| GDM-MRCR v2, 128k recall | 97.0% | 91.8% | 81.5% | 93.5% | 3.7 Flash |
| AA Intelligence Index | 56 | 52 | 55 | 57 | GPT-5.6 Terra |
Gemini 3.7 Flash beat Claude Sonnet 5 on every row of that table and lost three rows to GPT-5.6 Terra, the agent-coding ones among them. GPT-5.6 Terra kept a 4.3-point lead on DeepSWE. Claude Sonnet 5 trailed by 15.5 points on 128k recall, the widest gap in the table. Most of these numbers are Google's own runs.
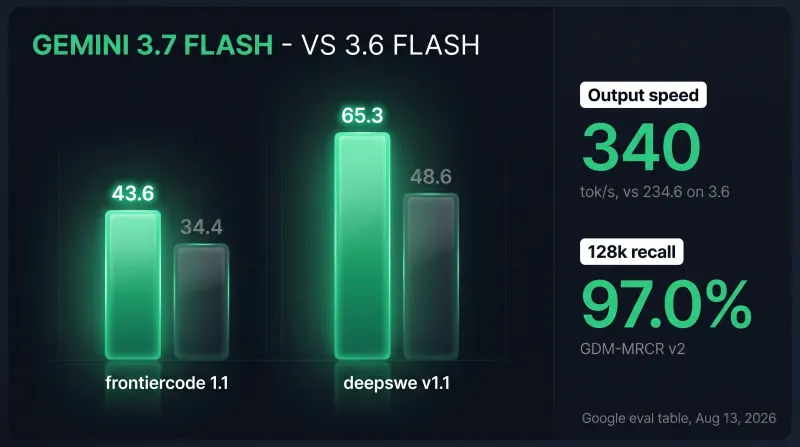
The speed bars in that chart come from our August write-up, which recorded about 340 output tokens per second for 3.7 Flash against roughly 234 for 3.6 Flash on Artificial Analysis. We could not recheck either figure today: Artificial Analysis now lists 3.7 Flash as deprecated with no publicly available API to measure. For scale, it currently clocks 3.8 Flash at 111 output tokens per second at high reasoning.
On Arena's text leaderboard (board dated November 11, 2026), Gemini 3.7 Flash at high thinking scores 1489±5 from 33,251 votes, still marked preliminary, for rank #17.
Gemini 3.7 Flash vs 3.6 Flash, and why 3.8 Flash replaced both
Against 3.6 Flash, 3.7 Flash was the clear upgrade: every row in the card above improved, by 16.7 points on DeepSWE alone. The Gemini 3.6 Flash API is still live and still on Google's price list, but on our card it costs more per token than 3.7 Flash, so it only makes sense for a pipeline tested against it.
The real comparison now is with the model Google routes 3.7 traffic to. From Google's September 2026 card for 3.8 Flash:
| Benchmark | Gemini 3.8 Flash | Gemini 3.7 Flash |
|---|---|---|
| DeepSWE v1.1 | 73.7% | 65.3% |
| Terminal-bench 2.1 | 89.4% | 85.8% |
| Terminal-bench 4.0 | 19.1% | 11.2% |
| Vals Finance Agent v2 | 61.4% | 59.0% |
| GDPVal-AA v2 (Elo) | 1545 | 1482 |
The Gemini 3.8 Flash API wins every row at the same per-token rate on our card, so there is no price reason to stay on 3.7. Google also notes that 3.8 Flash can spend more tokens on long, multi-step tasks by design, so run a sample through both before assuming the bill stays flat; lowering the reasoning level brings it back down.
Gemini 3.7 Flash pricing, launch pricing and what replaced it
Gemini 3.7 Flash API pricing on UnificAlly sits next to the two neighboring Flash models, per million tokens:
| Model | Option | Our rate |
|---|---|---|
| Gemini 3.7 Flash | input | $0.225/1M tokens |
| output | $1.125/1M tokens | |
| cache read | $0.0225/1M tokens | |
| Gemini 3.8 Flash | input | $0.225/1M tokens |
| output | $1.125/1M tokens | |
| cache read | $0.0225/1M tokens | |
| Gemini 3.6 Flash | input | $0.225/1M tokens |
| output | $1.125/1M tokens | |
| cache read | $0.0225/1M tokens |
On Google's side, 3.7 Flash launched on the same introductory schedule as 3.6 Flash, ending December 31, 2026, with standard rates from January 1, 2027. After the October 8 deprecation Google removed the 3.7 row, so anyone searching Gemini 3.7 Flash launch pricing today is really looking at 3.8 Flash's schedule, which carries the same end date. Gemini Flash pricing on Google counts thinking tokens as output, and so does every output line here.
Two worked costs at UnificAlly's Gemini 3.7 Flash price:
| Task | Tokens (in / out) | Input cost | Output cost |
|---|---|---|---|
| Review 1,000 pull requests at 6,000 tokens each | 6M / 600K | $1.35 | $0.675 |
| Describe 500 product videos of 30 seconds | 1.425M / 150K | $0.320625 | $0.16875 |
The video row uses the token rate in our docs: about 70 tokens per second of frames plus about 25 per second of audio, so a 30-second video comes to roughly 2,850 input tokens. The same jobs on 3.8 Flash cost the same per token. That makes the Gemini 3.7 Flash cost question a quality question.
Calling google/gemini-3.7-flash, or moving to 3.8 Flash
google/gemini-3.7-flash answers on /v1/chat/completions, /v1/responses and /v1/messages. Send LLM traffic to https://direct-api.unifically.com: our docs warn that the main api.unifically.com host sits behind a proxy whose timeout can cut a long answer short, and the generated tokens are billed anyway.
curl -X POST https://direct-api.unifically.com/v1/chat/completions \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer YOUR_API_KEY" \
  -d '{
    "model": "google/gemini-3.7-flash",
    "messages": [
      { "role": "user", "content": "Summarize the attached contract and list every obligation with a deadline." }
    ]
  }'
Moving to 3.8 Flash is a one-word change: "model": "google/gemini-3.8-flash". For video, add a video_url content part with a public https link; video works on Chat Completions only, and inline base64 has to stay under 20 MB. Set "stream": true to stream. Parameter details live on the Gemini 3.7 Flash docs page.
Gemini 3.7 Flash FAQ
What model ID does Gemini 3.7 Flash use?
google/gemini-3.7-flash on UnificAlly, sent to POST /v1/chat/completions, /v1/responses or /v1/messages with a UnificAlly API key. On Google's own API the ID is gemini-3.7-flash, and Google now routes those calls to Gemini 3.8 Flash.
Is Gemini 3.7 Flash better than Gemini 3.6 Flash?
Yes. In Google's model card it improved on every listed benchmark: DeepSWE v1.1 from 48.6% to 65.3%, FrontierCode 1.1 from 34.4% to 43.6% and 128k recall from 91.8% to 97.0%. Gemini 3.8 Flash has since overtaken both.
How fast is Gemini 3.7 Flash?
There is no current measurement. Our August launch write-up recorded about 340 output tokens per second from Artificial Analysis, but that site now marks Gemini 3.7 Flash deprecated and shows no live figure. It measures Gemini 3.8 Flash at 111 output tokens per second at high reasoning.
What is the Gemini 3.7 Flash context window?
Gemini 3.7 Flash accepts 1,048,576 input tokens and returns up to 65,536 output tokens. Google's card reports 97.0% recall on GDM-MRCR v2 at 128k tokens, ahead of GPT-5.6 Terra at 93.5% and Claude Sonnet 5 at 81.5%.
What is the Gemini 3.7 Flash knowledge cutoff?
March 2026, according to Google's model card, with a caveat: in some domains the model's knowledge only reaches January 2025, in line with the rest of the Gemini 3 family. Plan retrieval or search grounding for anything newer.
Is there a Gemini 3.7 Pro?
No. Google's model list has no Gemini 3.7 Pro. The newest Pro-named model in the Gemini API is still Gemini 3.1 Pro Preview, and Google's larger models now ship under Gemini 4 names: Gemini 4 Argon on October 13, 2026, then Carbon and Hydrogen in November.
How long does the launch pricing last?
Google's introductory pricing for the 3.6 and 3.7 Flash generation ends on December 31, 2026, with standard rates from January 1, 2027. Since 3.7 Flash requests now route to 3.8 Flash on Google, that model's identical schedule is the one that applies there. UnificAlly's rate is in the table above.
For the whole Google lineup, rates included, see the Gemini API pricing guide. The Gemini 3.8 Flash API playground runs the replacement with no code.