OpenAI API pricing: what every GPT model costs per million tokens, and which one is worth paying for
OpenAI API pricing per 1M tokens for GPT 6 Astra, Sol, Luna and GPT 5: input, output, cache and long-context rates, real request costs, and which to pick.
OpenAI API pricing is billed per token: one rate for the tokens you send, a higher rate for the tokens the model writes, and a lower rate for input it has already cached. The "ChatGPT API" people search for is the same thing, OpenAI's Chat Completions endpoint, billed the same way. UnificAlly serves the current GPT 6 and GPT 5 models on that request format, below OpenAI's list rates, with the GPT 6.1 Sol API at $0.30 / $1.50 per million input / output tokens and GPT 6 Luna from $0.015 per million input tokens. This guide lists every model's rate, explains the long-context and cache rules that change the bill, and works through what real requests cost.
TL;DR: On UnificAlly, GPT models cost per 1M tokens (input / output, prompts up to 272k tokens) $1.50 / $7.50 (GPT 6 Astra), $0.30 / $1.50 (GPT 6.1 Sol) and $0.015 / $0.075 (GPT 6 Luna), below OpenAI's list price on every model. Our pick: GPT 6.1 Sol for almost everything. It matches GPT 6 Astra on coding benchmarks, and at today's rates it costs less per token than GPT 5.6 Sol, GPT 5.6 Terra, GPT 5.5 and GPT 5.4 while scoring higher, so paying more for an older GPT buys you nothing. New accounts get $0.50 of balance on signup. See live rates on the pricing page.
OpenAI API pricing per model (2026)
OpenAI's own rates are published on OpenAI's API pricing page. Two things on that page are worth knowing before you budget. First, GPT 5.6 Sol is on promotional list pricing that OpenAI says runs at least through November 21, 2026, so its first-party rate may go back up after that. Second, OpenAI priced GPT 6 Sol and GPT 6 Luna below their GPT 5.6 counterparts when they launched on September 22, 2026, which is why the newest Sol and Luna models are also the cheapest of their size to run.
UnificAlly prices each of these GPT language models below OpenAI's list rate. GPT model pricing on UnificAlly, per million tokens, for prompts up to 272k tokens:
| Model | Input | Cached input | Output |
|---|---|---|---|
| GPT 6 Astra | $1.50 | $0.15 | $7.50 |
| GPT 6.1 Sol | $0.30 | $0.015 | $1.50 |
| GPT 6 Sol | $0.30 | $0.03 | $1.50 |
| GPT 6 Luna | $0.015 | $0.0015 | $0.075 |
| GPT 5.6 Sol | $0.75 | $0.075 | $4.50 |
| GPT 5.6 Terra | $0.375 | $0.0375 | $2.25 |
| GPT 5.6 Luna | $0.15 | $0.015 | $0.90 |
| GPT 5.5 | $0.75 | $0.075 | $4.50 |
| GPT 5.4 | $0.375 | $0.0375 | $2.25 |
That table answers most GPT API pricing questions at a glance: GPT 6 Luna is the cheapest OpenAI API option by a wide margin, GPT 6 Astra is the most expensive, and the GPT 6 Sol line sits in between. Every model page also lists its own rate card and has a browser playground. Every OpenAI model we serve is listed on one page in the OpenAI API overview.
Which GPT model to pay for
Our call, based on OpenAI's published DeepSWE v1.1 scores (long software tasks in real codebases) and the rates above:
| Model | DeepSWE v1.1 |
|---|---|
| GPT 6.1 Sol | 75.2% |
| GPT 6 Astra | 74.1% |
| GPT 5.6 Sol (max effort) | 72.7% |
| GPT 6 Sol | 68.8% |
| GPT 6 Luna (max effort) | 66.6% |
| GPT 5.6 Luna | 62.2% |
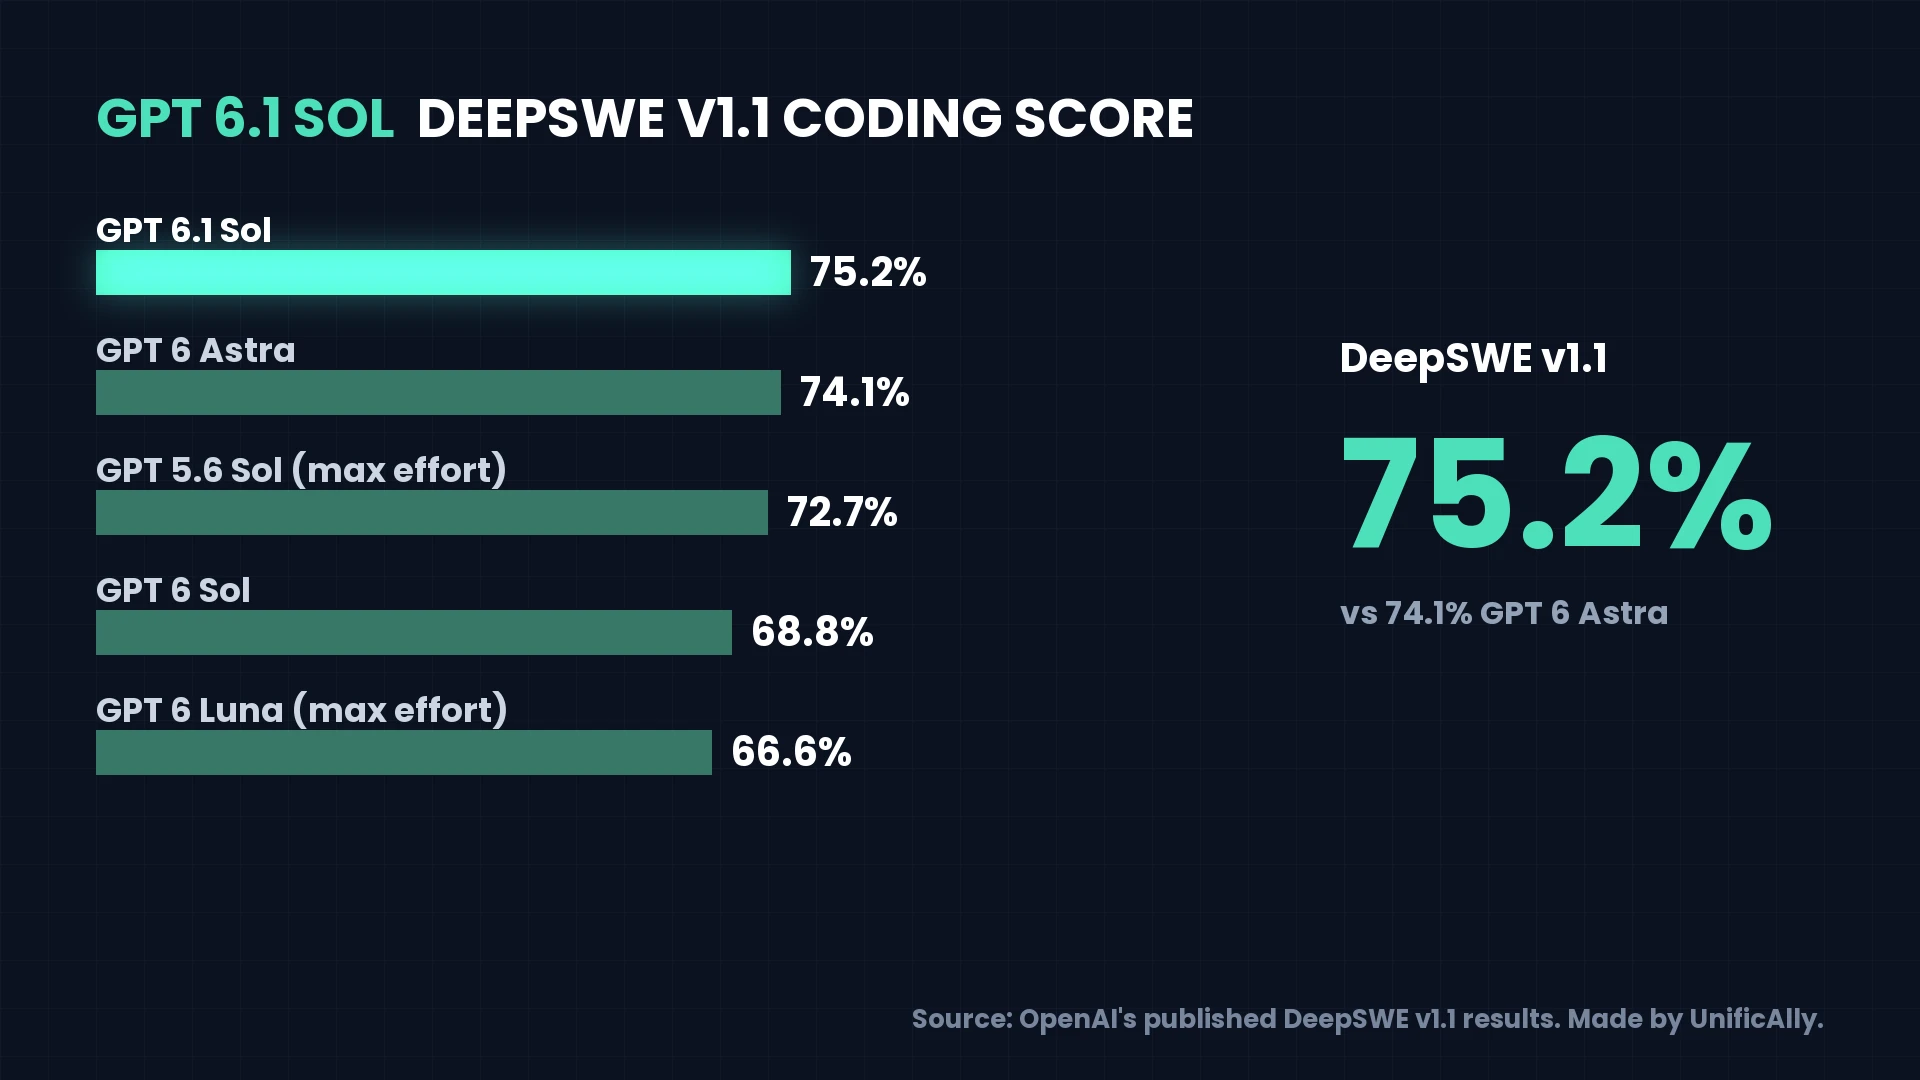
- GPT 6.1 Sol is the default. It edges GPT 6 Astra on DeepSWE (75.2% against 74.1%) and lands about two points behind it on OSWorld 2.0, at a fraction of Astra's per-token rate. It also replaces GPT 6 Sol outright: same input and output price, higher scores on every benchmark OpenAI published, and cheaper cached input.
- GPT 6 Astra is worth its price only for the work where it still clearly leads. On Terminal-Bench Science 0.1 it scores 68.1% against 57.0% for GPT 6.1 Sol. If your workload looks like that, pay for Astra. If it looks like coding or tool use, you are overpaying.
- GPT 6 Luna is the cheap OpenAI API for volume: classification, extraction, routing, draft patches. It is the small model and it shows on harder work (Artificial Analysis puts its Coding Agent Index two points below GPT 5.6 Luna), so do not hand it your hardest tasks.
- The GPT 5 line only makes sense for pipelines already tuned and regression-tested against it. At today's rates GPT 5.6 Sol, GPT 5.6 Terra, GPT 5.5 and GPT 5.4 each cost more per input token than GPT 6.1 Sol, and the best of them, GPT 5.6 Sol, scores lower on DeepSWE. GPT 5.6 Luna is cheaper than GPT 6.1 Sol but costs more than GPT 6 Luna and scores below it. That is the part of OpenAI's lineup we would move off first.
What surprised us is how little Astra buys. The habit is to default to the flagship; on these numbers the mid model is the better engineering choice and the cheaper one.
How OpenAI token pricing works (input, output, cache, long context)
Every GPT request bills up to four things:
- Input tokens. System prompt, conversation history, documents, tool definitions. Billed at the input rate.
- Output tokens. Everything the model writes back, including reasoning tokens the response does not show you. Output costs several times the input rate on every GPT model, so a model that thinks at high effort can cost more than its input rate suggests.
- Cached input. A repeated prompt prefix (a fixed system prompt, a tool list, a long document) is read from cache at a small fraction of the input rate.
- Cache writes. On the GPT 6 and GPT 5.6 models, writing a prefix into the cache bills slightly above plain input.
The detail that changes OpenAI token pricing the most is the 272k long-context line. On GPT 6 Astra, GPT 6.1 Sol, GPT 6 Sol, GPT 6 Luna and the GPT 5.6 models, once a request's prompt passes 272,000 tokens the whole request bills at the long-context rate: double on input, cached input and cache writes, and 1.5x on output. The full rate card for GPT 6.1 Sol shows both tiers:
| Model | Option | Our rate |
|---|---|---|
| GPT 6.1 Sol | input (prompt up to 272k) | $0.30/1M tokens |
| output (prompt up to 272k) | $1.50/1M tokens | |
| cache read (prompt up to 272k) | $0.015/1M tokens | |
| cache creation (prompt up to 272k) | $0.375/1M tokens | |
| input (prompt over 272k) | $0.60/1M tokens | |
| output (prompt over 272k) | $2.25/1M tokens | |
| cache read (prompt over 272k) | $0.03/1M tokens | |
| cache creation (prompt over 272k) | $0.75/1M tokens |
Growing a prompt from 270k to 300k tokens therefore reprices the whole request at the higher tier, not just the extra 30k tokens. Trim retrieval results and history to stay under the line where you can, and keep a stable system prompt at the front so it caches.
OpenAI also sells processing tiers on its own API. Batch and Flex bill at half the standard rate for work that can wait, Fast mode (called Priority until July 30, 2026) bills at double for lower latency, and regional data-residency endpoints add 10% for models released on or after March 5, 2026. If you search for OpenAI Batch API pricing, that half-price rule is the answer on OpenAI's side; the rates in this post are UnificAlly's standard per-request rates.
OpenAI API cost examples (what a real request costs)
The OpenAI API cost of a task follows from its token counts. Four worked examples at UnificAlly rates, all with prompts under 272k tokens:
| Task | Tokens (in / out) | Input cost | Output cost |
|---|---|---|---|
| Answer one question over 8k tokens of retrieved docs, GPT 6.1 Sol | 9,000 / 600 | $0.0027 | $0.0009 |
| Review a 2,000-line diff, GPT 6 Astra | 40,000 / 3,000 | $0.06 | $0.0225 |
| Tag 100,000 product titles, GPT 6 Luna | 5M / 500K | $0.075 | $0.0375 |
| Support bot for a month, GPT 6.1 Sol | 30M / 5M | $9 | $7.50 |
A single request costs a fraction of a cent on GPT 6.1 Sol and GPT 6 Luna, and even an Astra code review stays well under a dollar. The ChatGPT API cost of a production app is a volume question: multiply your monthly tokens by the rates in the table, then cut the input side with caching.
GPT Image pricing
OpenAI's API price list also covers image generation. On UnificAlly the GPT Image models bill per image by resolution:
| Model | Option | Our rate |
|---|---|---|
| GPT Image 2 | 1K | $0.03 |
| 2K | $0.05 | |
| 4K | $0.08 | |
| GPT Image 2.5 Flare | 1K | $0.03 |
| 2K | $0.05 | |
| 4K | $0.08 | |
| GPT Image 2.5 Sunburst | 1K | $0.04 |
| 2K | $0.07 | |
| 4K | $0.11 |
The GPT Image 2 pricing guide breaks those rates down with examples, and the GPT Image 2.5 API page covers the Flare and Sunburst variants.
How to access the OpenAI API
Two routes:
- OpenAI directly. Create a key on OpenAI's platform and call
api.openai.comat OpenAI's list prices, with access to Batch, Flex and Fast mode. - UnificAlly. One API key covers GPT alongside Claude, Gemini, image, video and audio models, billed pay-per-use from a single balance. No subscription, and balance does not expire. GPT models take the OpenAI-compatible
/v1/chat/completionsrequest. UnificAlly is an independent API, not affiliated with OpenAI: you use a UnificAlly key and balance, not an OpenAI account.
A working request against GPT 6.1 Sol:
curl -X POST https://api.unifically.com/v1/chat/completions \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer YOUR_API_KEY" \
  -d '{
    "model": "openai/gpt-6.1-sol",
    "messages": [
      {"role": "user", "content": "Review this pull request and list any bugs you find."}
    ]
  }'
Swap the model id for any row in the table (openai/gpt-6-astra, openai/gpt-6-luna, openai/gpt-5.5, and so on). Existing OpenAI SDK code works by pointing base_url at https://api.unifically.com/v1 and using a UnificAlly API key.
OpenAI FAQ
How much does the OpenAI API cost?
On UnificAlly, per million tokens (input / output, prompts up to 272k tokens): $1.50 / $7.50 for GPT 6 Astra, $0.30 / $1.50 for GPT 6.1 Sol, and $0.015 / $0.075 for GPT 6 Luna, all below OpenAI's list prices. A typical single request costs well under a cent on GPT 6.1 Sol.
Is the ChatGPT API pricing different from OpenAI API pricing?
No. "ChatGPT API" is the common name for OpenAI's Chat Completions API, and it bills per token like every other OpenAI endpoint. ChatGPT Plus, Pro and Business are subscriptions billed per seat, which is a different price list from the API's per-token rates.
Is the OpenAI API free?
No. Both OpenAI and UnificAlly bill per token. You can test GPT models on UnificAlly with the $0.50 balance new accounts get on signup, which covers tens of millions of GPT 6 Luna input tokens or over a million GPT 6.1 Sol input tokens. There is no subscription, and unused balance does not expire.
What is the cheapest OpenAI API model?
GPT 6 Luna: $0.015 input / $0.075 output per million tokens on UnificAlly, below OpenAI's list price. It is OpenAI's fastest GPT 6 model, built for high-volume work like classification and extraction.
What does GPT 6.1 Sol cost per million tokens?
On UnificAlly, GPT 6.1 Sol costs $0.30 input / $1.50 output per million tokens, with cached input at $0.015, for prompts up to 272k tokens. Longer prompts bill the whole request at the long-context rate shown in the rate card above.
Why is OpenAI API pricing different from what I pay on UnificAlly?
OpenAI's API pricing is the first-party list rate. UnificAlly resells the same models at lower per-token rates, below OpenAI's list price on every GPT model. The request and response formats are the same, so switching is a base-URL and API-key change.
Do cached tokens cost less?
Yes. On UnificAlly, GPT 6.1 Sol cached input is $0.015 per million tokens against $0.30 for fresh input, so an app with a large, stable system prompt saves most of its input spend.
Our rates in this post come from UnificAlly's live price list and refresh on every deploy. OpenAI's own list prices are on OpenAI's pricing page. We will update this post when GPT 5.6 Sol's promotional list price ends, when OpenAI releases a new GPT model, and when new GPT models land on UnificAlly. Comparing providers? See the Claude API pricing guide and the Gemini API pricing guide, or check every rate at once on the pricing page.