DeepSeek API pricing: what V4 Pro and V4 Flash cost, peak and off-peak
DeepSeek pricing per 1M tokens for V4 Pro and V4 Flash: peak and off-peak rates, cache-hit discounts, the August 2026 price rise, and how to call the API.
DeepSeek's API currently serves two models: deepseek-flash (V4.1 Flash, upgraded to the 1017 build on October 17, 2026) and deepseek-v4-pro, both from the V4 family that replaced V3.2 this spring. The preview launched on April 24, 2026, the final V4-Flash landed on July 31, V4-Pro reached general availability on August 13, and V4.1 Flash replaced V4 Flash on September 10. Both models take 1M tokens of context, return up to 384K tokens of output, and publish open weights under the MIT license. Peak and off-peak API pricing took effect on August 16 and the Flash rates were lowered again in September, so most numbers you find in older posts are already wrong. Here is the current picture, verified against DeepSeek's own change log on October 19, 2026.
TL;DR: Yes, there is a public DeepSeek API at platform.deepseek.com. The current models are
deepseek-v4-flashanddeepseek-v4-pro, both with 1M context and 384K max output. Since August 16, 2026, DeepSeek bills peak and off-peak rates by time of day, several times its old flat prices, so any budget written before August needs a re-check. DeepSeek is live on UnificAlly: the DeepSeek V4 Pro API costs $0.51/1M tokens input and $1.52/1M tokens output off-peak, and DeepSeek V4.1 Flash and the legacy deepseek-v4-flash model ID cost $0.1125/1M tokens input and $0.45/1M tokens output. They run on the same key as Claude Fable 5, GPT 5.6 Sol, and Kimi K3.
Is there a DeepSeek API?
Yes. DeepSeek runs its own API platform at platform.deepseek.com, documented at api-docs.deepseek.com. You create an API key, top up a balance, and pay per token. There is no subscription.
The API speaks two formats from the same account:
- OpenAI-compatible: base URL
https://api.deepseek.com, works with the standard OpenAI SDKs. - Anthropic-compatible: base URL
https://api.deepseek.com/anthropic, for tools built against the Anthropic API.
Both current models support JSON output, tool calls, and the OpenAI Responses API format, which DeepSeek added at the V4-Pro GA release with a one-click Codex setup. Thinking mode is on by default and can be switched off per request; since August 13 the thinking effort has three levels (low / high / max).
DeepSeek V4 release date and the current lineup
"DeepSeek 4" officially means the DeepSeek-V4 family. The release rolled out in stages during 2026, all dated in DeepSeek's change log:
| Date | What happened |
|---|---|
| April 24, 2026 | V4 preview launch. deepseek-v4-pro and deepseek-v4-flash go live on the API, open-sourced from day one |
| July 24, 2026 | Legacy model names deepseek-chat and deepseek-reasoner retired |
| July 31, 2026 | Final DeepSeek-V4-Flash-0731 released (public beta), re-post-trained on the same architecture |
| August 13, 2026 | DeepSeek-V4-Pro-0813 reaches GA on app, web, and API |
| August 16, 2026 | New peak/off-peak API pricing takes effect |
| September 10, 2026 | DeepSeek-V4.1-Flash released: the smallest model of the new architecture family, with native visual understanding. New model name deepseek-flash; V4 Flash retired, with deepseek-v4-flash routed to V4.1 Flash. Flash API prices lowered |
| October 17, 2026 | DeepSeek-V4.1-Flash-1017 upgrade on the same name and prices, with shorter task runtimes and outputs. DeepSeek's in-house Search & Fetch API launches |
So as of October 19, 2026, DeepSeek's newest checkpoint is DeepSeek-V4.1-Flash-1017 and its flagship is DeepSeek-V4-Pro-0813. The two live API models are:
- DeepSeek-V4-Pro: 1.6T total parameters, 49B active per token. The flagship, aimed at agent work and hard reasoning.
- DeepSeek-V4-Flash: 284B total, 13B active. The fast, cheap option, and by DeepSeek's own numbers surprisingly close to Pro on agent tasks.
Both use a sparse mixture-of-experts design with a new attention stack (token-wise compression plus DeepSeek Sparse Attention) that makes the 1M-token context window practical. The model card reports single-token inference cost at 27% of DeepSeek-V3.2's FLOPs in million-token contexts. Weights for both models are on Hugging Face under the MIT license, so self-hosting and fine-tuning are allowed, commercially included.
DeepSeek API pricing
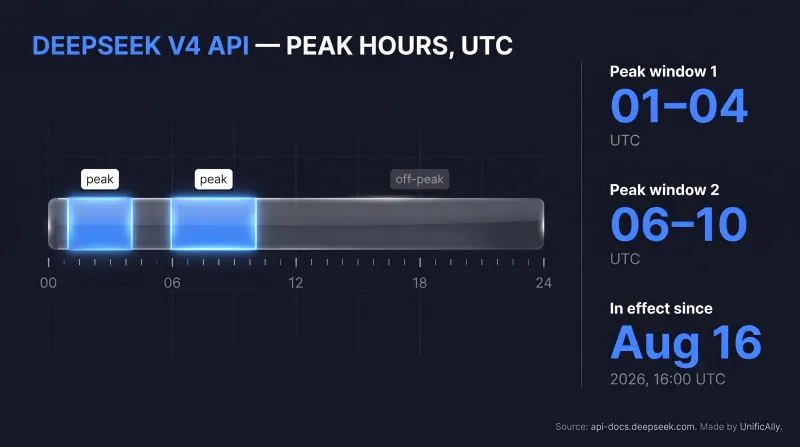
DeepSeek's current pricing took effect at 16:00 UTC on August 16, 2026. The unusual part: rates change by time of day. Peak hours are 01:00-04:00 and 06:00-10:00 UTC; every other hour is off-peak at a lower rate. UnificAlly follows the same schedule, and these are our current rates per 1M tokens:
| Per 1M tokens (UnificAlly) | V4-Flash peak | V4-Flash off-peak | V4-Pro peak | V4-Pro off-peak |
|---|---|---|---|---|
| Input, cache miss | $0.225 | $0.1125 | $1.02 | $0.51 |
| Input, cache hit | $0.0045 | $0.00225 | $0.034 | $0.017 |
| Output | $0.90 | $0.45 | $3.04 | $1.52 |
Context caching is automatic. A cache hit on repeated input costs a small fraction of the miss price, which matters a lot for agents that resend a growing transcript every turn. One worked example: a request sending 100K fresh input tokens and returning 10K tokens on V4-Flash off-peak costs $0.01125 for the input plus $0.0045 for the output. The same request at peak costs $0.0225 plus $0.009.
Two operational limits worth knowing before you build on it: concurrency is capped at 2,500 parallel requests for V4-Flash and 500 for V4-Pro, and reasoning tokens bill as output, so thinking mode at max effort raises real output volume well past the visible answer.
If you schedule batch work, the off-peak window is a real discount: the same job costs less outside 01:00-10:00 UTC. DeepSeek's own list prices are on its pricing page.
DeepSeek pricing compared: V4 Pro, V4.1 Flash, Kimi K3 and GPT-6 Luna
"DeepSeek pricing" is usually a comparison question in disguise: cheaper than what? The two models most often weighed against it in October 2026 are Kimi K3, the other large open-weights MoE, and GPT-6 Luna, OpenAI's low-cost tier. All four run on one UnificAlly key; these are our off-peak rates per 1M tokens, refreshed from the live price list on every deploy.
| Per 1M tokens (UnificAlly, off-peak) | DeepSeek V4 Pro | DeepSeek V4.1 Flash | Kimi K3 | GPT-6 Luna |
|---|---|---|---|---|
| Model ID | deepseek/deepseek-v4-pro | deepseek/deepseek-flash | moonshotai/kimi-k3 | openai/gpt-6-luna |
| Input, cache miss | $0.51 | $0.1125 | $2.25 | $0.015 |
| Input, cache hit | $0.017 | $0.00225 | $0.225 | $0.0015 |
| Output | $1.52 | $0.45 | $11.25 | $0.075 |
| Peak-hour surcharge | Yes (01:00-04:00, 06:00-10:00 UTC) | Yes, same windows | No | No |
| Context | 1M | 1M | 1M | See model page |
| Open weights | MIT | MIT | Yes | No |
| Parameters | 1.6T total, 49B active | 284B total, 13B active (V4 Flash figures) | 2.8T MoE | Not published |
Two readings. Against Kimi K3, DeepSeek wins on price at every line and K3 wins on Arena chat preference (#12 vs #51 in August). Against GPT-6 Luna, OpenAI's budget tier, V4.1 Flash is not the cheapest line on this card, so the DeepSeek case there is the 1M context, the agent benchmarks and the MIT weights rather than the invoice. For a worked example, 100K fresh input tokens plus 10K output on V4.1 Flash off-peak is $0.01125 plus $0.0045.
How much did DeepSeek raise prices?
A lot. Until August 16, DeepSeek charged flat rates around the clock on both V4 models, per Reuters and Fortune. Under the new structure, output on both V4-Flash and V4-Pro costs several times the old flat rate at peak, and more than double it even off-peak.
Flash input moved the same way. DeepSeek warned developers on August 6 that an increase was coming, and it had trialed time-of-day discounts in mid-July before making the two-tier structure official.
Two practical takeaways. First, the off-peak window now does the work the flat price used to do: for teams in US time zones, normal business hours land off-peak, so interactive traffic mostly sees the lower rates. Second, if your budget was built on the old flat output rate, a peak-hour agent workload now costs several times what it did in July. Re-run the math before the invoice does it for you.
DeepSeek V4 benchmarks
DeepSeek published agent-focused numbers for both final checkpoints in its change log. Its own comparison shows why Flash is interesting: it holds most of Pro's agent capability at a fraction of the price.
| Benchmark (vendor-run) | V4-Flash-0731 | V4-Pro-0813 |
|---|---|---|
| Terminal Bench 2.1 | 82.7 | 87.9 |
| DeepSWE | 54.4 | 62.7 |
| NL2Repo | 54.2 | 61.5 |
| Cybergym | 76.7 | 83.3 |
| Toolathlon-Verified | 70.3 | 74.1 |
| Agents' Last Exam | 25.2 | 25.7 |
| AutomationBench (Public) | 25.1 | 31.8 |
V4-Pro also reports HLE at 42.7 without tools and 60.0 with tools. The Hugging Face model card adds, for Pro at max reasoning: 80.6 on SWE-bench Verified, 93.5 on LiveCodeBench, a 3206 Codeforces rating, and 83.5 on the 1M-token MRCR long-context test.
Read the fine print, though. DeepSeek notes the code-agent results were run on its own "DeepSeek Harness" in minimal mode at max effort, and that harness is not yet public. Until it is released and third parties reproduce the scores, treat the agent table as the vendor's numbers, not settled fact.
Independent crowd voting tells a more modest story. On Arena's Text leaderboard, pulled August 18, 2026, deepseek-v4-pro sits at 1458 Elo, rank #51 overall on 54,397 votes, and deepseek-v4-flash at 1435, rank #85. Claude Fable 5 leads the board at 1506, and Kimi K3 (max effort) holds #12 at 1489, which currently makes Kimi the stronger open-weights model by Arena's measure. V4 Pro's strength is agent benchmarks and price, not chat preference votes.
How to access the DeepSeek API
- Sign up at platform.deepseek.com and top up a balance.
- Create an API key under API Keys.
- Point an OpenAI SDK at DeepSeek's base URL:
from openai import OpenAI

client = OpenAI(
    api_key="YOUR_DEEPSEEK_API_KEY",
    base_url="https://api.deepseek.com",
)

response = client.chat.completions.create(
    model="deepseek-v4-flash",
    messages=[{"role": "user", "content": "Summarize this changelog in three bullets."}],
)
print(response.choices[0].message.content)
Swap the model name to deepseek-v4-pro for the flagship. For Anthropic-format tools, use https://api.deepseek.com/anthropic as the base URL instead.
One migration note: the old deepseek-chat and deepseek-reasoner model names were retired on July 24, 2026. If an integration built before April still uses them, it now fails; update the model parameter to one of the V4 names.
Is DeepSeek on UnificAlly? Yes, plus alternatives on one API
Yes. Since September 2026 UnificAlly serves DeepSeek V4 Pro, DeepSeek V4.1 Flash, and the deepseek-v4-flash ID, which DeepSeek now answers with V4.1 Flash. Billing follows the same peak and off-peak schedule, and live rates are on each model page and the pricing page.
If you want to compare DeepSeek with other language models on the same key and balance you use for image, video, and audio generation, these are the closest live options:
- Claude Fable 5: #1 on Arena's Text board at 1506 Elo. The strongest general model you can call on UnificAlly, and the reference point V4-Pro gets measured against.
- Kimi K3: the closest analog to what DeepSeek offers, a huge open-weights MoE (2.8T parameters, 1M context) priced at $2.25/1M tokens input and $11.25/1M tokens output on UnificAlly. Our Kimi K3 review has the full benchmark picture.
- GPT 5.6 Sol: OpenAI's agent-focused model, a direct rival to V4-Pro on terminal and coding-agent work.
Live rates for every model are on the pricing page. Billing is pay-per-use with no subscription, and new accounts get a $0.50 balance to test with.
DeepSeek FAQ
What is DeepSeek's latest model?
DeepSeek-V4-Pro-0813, released to general availability on August 13, 2026. It is the flagship of the DeepSeek 4 family; DeepSeek-V4-Flash-0731 is the smaller, cheaper sibling from July 31.
Is the DeepSeek API free?
No, it bills per token from a prepaid balance. The weights are a different story: both V4 models are downloadable from Hugging Face under the MIT license, so running them on your own hardware costs nothing in license fees.
What is the DeepSeek V4 context window?
1M tokens for both V4-Pro and V4-Flash, with a maximum output of 384K tokens. Context caching is automatic, and cached input bills at a small fraction of the cache-miss rate.
Why did my deepseek-chat API calls stop working?
DeepSeek retired the deepseek-chat and deepseek-reasoner model names on July 24, 2026. Set the model parameter to deepseek-v4-flash (or deepseek-v4-pro) instead; the base URL is unchanged.
Does the DeepSeek V4 API cost more at certain hours?
Yes. Since August 16, 2026, DeepSeek bills peak rates during 01:00-04:00 and 06:00-10:00 UTC and a lower rate at all other hours. Scheduling batch jobs off-peak cuts the bill.
Why is DeepSeek so much cheaper?
Architecture and licensing. Both V4 models are sparse mixture-of-experts: V4-Flash activates about 13B of its 284B parameters per token and V4-Pro 49B of 1.6T, and DeepSeek's sparse attention keeps 1M-token contexts affordable (the model card puts V4-Pro's per-token inference at 27% of V3.2's FLOPs at that length). Open MIT weights also mean other hosts compete on serving cost. The result on UnificAlly is $0.1125/1M tokens input and $0.45/1M tokens output off-peak for V4.1 Flash.
Is DeepSeek cheaper than ChatGPT?
For API use, yes against OpenAI's frontier tier: on UnificAlly, V4.1 Flash costs $0.45 per 1M output tokens off-peak against $4.50 for GPT-5.5. Against OpenAI's budget GPT-6 Luna it is not (see the comparison table above), so compare on context, benchmarks and weights there. For the chat apps the question is moot: DeepSeek's own chat app has no paid consumer tier.
Is the DeepSeek app free?
Yes. The web and mobile DeepSeek chat app is free to use with no subscription tier; only the API bills per token. The 1017 build of V4.1 Flash is the model behind the app as of October 17, 2026.
Did DeepSeek raise API prices in 2026?
Yes, sharply. On August 16, 2026, DeepSeek replaced its flat rates with peak/off-peak pricing. Output on both V4-Flash and V4-Pro now costs several times the old flat rate at peak, and more than double it off-peak. The change ended the flat ultra-cheap pricing DeepSeek was known for.
Things that will change this post: independent replications once DeepSeek releases its evaluation harness, Arena ranks as votes accumulate on the 0813 checkpoint, any further V4 checkpoints or pricing revisions, and new DeepSeek models joining V4 Pro and V4.1 Flash, which UnificAlly has served since September 2026. We will update it when they happen.